Does Duplicate Content Hurt SEO? What Google Actually Says
Google doesn't penalise ordinary duplicate content, but it can split ranking signals and waste crawling. Here's what Google says, what's risky and how to fix it.
No, not in the way most people fear. Google says there's no "duplicate content penalty" for ordinary duplication, such as the same page loading at several URLs. What duplication can do is let Google choose a different URL to show than the one you'd pick, split signals like links across several versions, and waste crawling time. The real risk is copying other people's content without adding anything, which Google's spam policies treat as manipulation.
Here's how Google handles duplicate content, when it becomes a problem, and how to tidy it up.
Is there a duplicate content penalty?
Not for the everyday kind. Google's Search Central blog addressed this directly in a post titled Demystifying the "duplicate content penalty": "There's no such thing as a 'duplicate content penalty.' At least, not in the way most people mean when they say that." The post explains that duplicate content on a site "is not grounds for action on that site unless it appears that the intent of the duplicate content is to be deceptive and manipulate search engine results."
Google's current documentation on canonicalization says the same thing in plainer words: "Some duplicate content on a site is normal and it's not a violation of Google's spam policies."
So if your online shop shows the same product at two URLs because of a filter, you haven't broken a rule. You've created a small housekeeping job.
The same product reachable through several filters is housekeeping, not a rule broken. Photo: Ashim D'Silva, CC0, via Wikimedia Commons.
What counts as duplicate content?
Google defines it loosely: pages that seem to be the same, or whose primary content is very similar. Its canonicalization page lists the usual causes:
Region variants, such as separate US and UK pages with essentially the same content in the same language.
Device variants, such as separate mobile and desktop versions of a page.
Protocol variants, such as the HTTP and HTTPS versions of a site.
Site functions, such as the results of sorting and filtering a category page.
Accidental variants, such as a demo or staging version of the site left open to crawlers.
Translated pages are a special case. Google treats different language versions as duplicates only if the main content stays in the same language, for example when just the navigation and footer are translated.
How does Google handle duplicate pages?
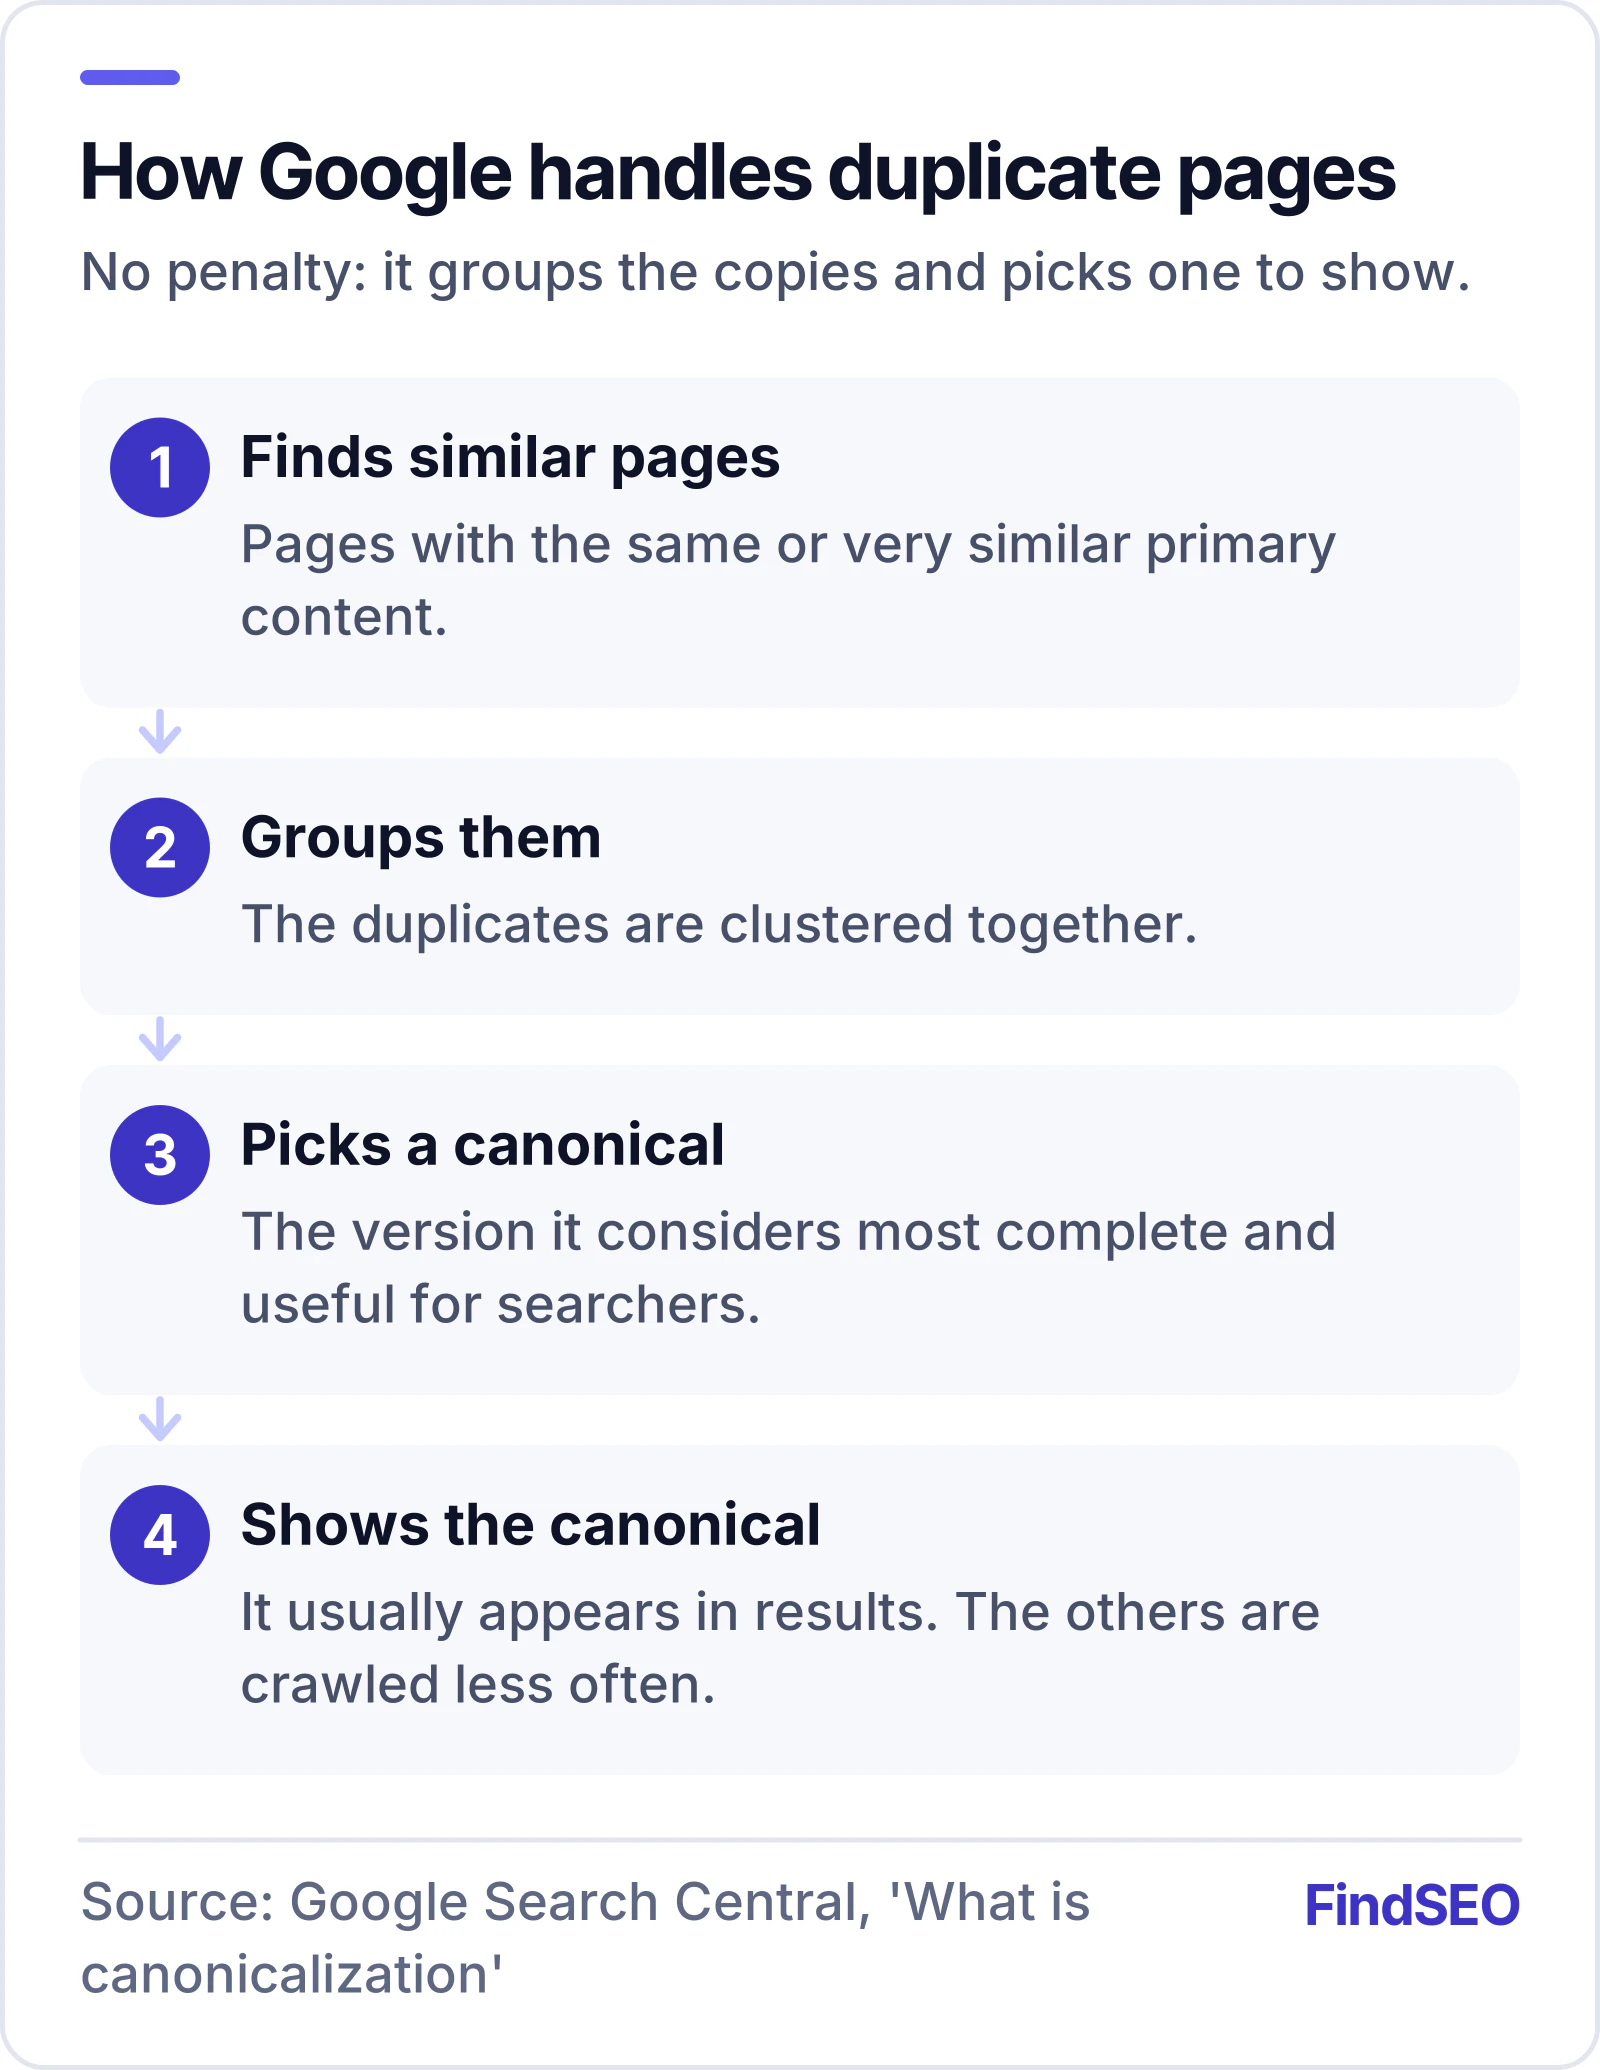
Google groups them and picks one. When it finds several pages with the same or very similar primary content, it clusters them and chooses the one it considers most complete and useful for searchers as the canonical URL. That's the version that usually appears in results, and Google uses it as the main source for evaluating the content's quality. The duplicates are crawled less often.
Canonical tags and redirects help Google pick the URL you'd choose.
Our Academy lesson on how search engines work covers crawling and indexing in more depth if the terms are new.
When does duplicate content actually cause problems?
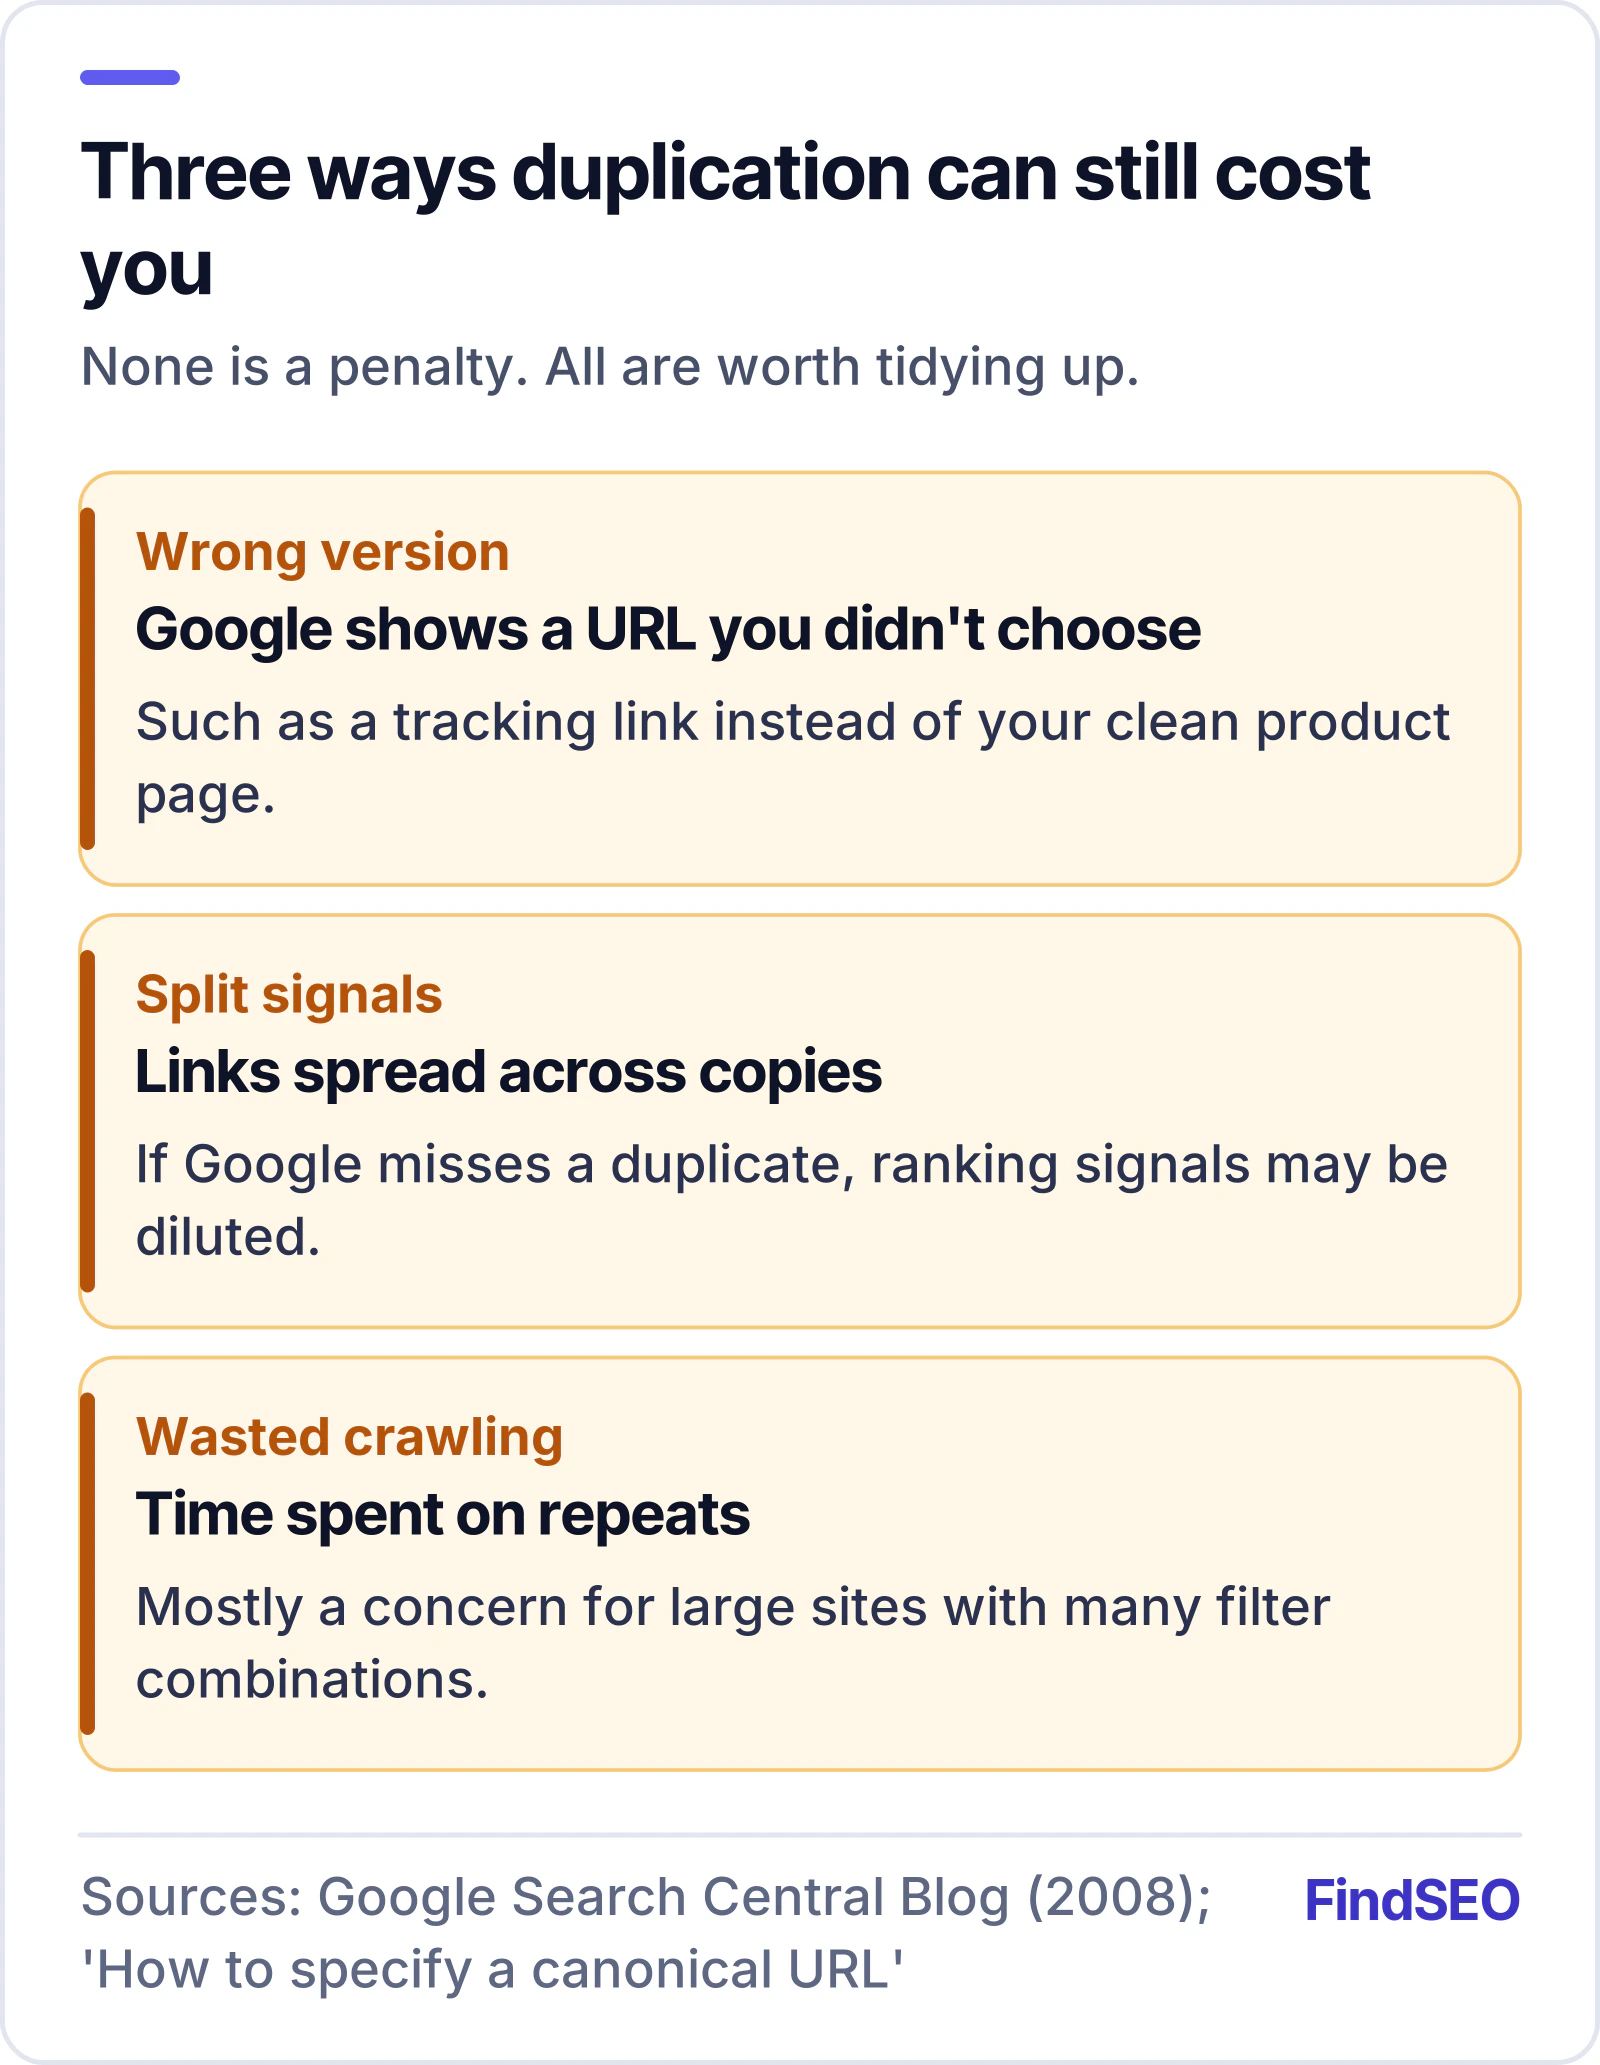
Even without a penalty, duplication can cost you in three ways that the 2008 post and Google's guide to specifying a canonical URL both describe.
For most small sites, the first two matter far more than crawl time.
Google may show the wrong version
Google's choice of the "best" URL might not match yours. A tracking link like /dresses/cocktail?gclid=ABCD could appear in results instead of your clean product URL, which looks untidy and can muddle your analytics.
Signals can be split
Google consolidates signals such as links into the canonical URL. If it doesn't detect every duplicate, those signals stay spread across several URLs, which the 2008 post says "may dilute the strength of that content's ranking signals."
Crawling time is wasted
Googlebot has to crawl each URL before it knows two pages are the same. On a large site with thousands of filter combinations, that's time not spent finding your new and updated pages. Our glossary entry on crawl budget explains when this matters; for most small sites it doesn't.
A related issue is keyword cannibalisation: several different pages written for the same search. They aren't duplicates in Google's technical sense, but they can compete with each other in a similar way.
When does copied content break Google's rules?
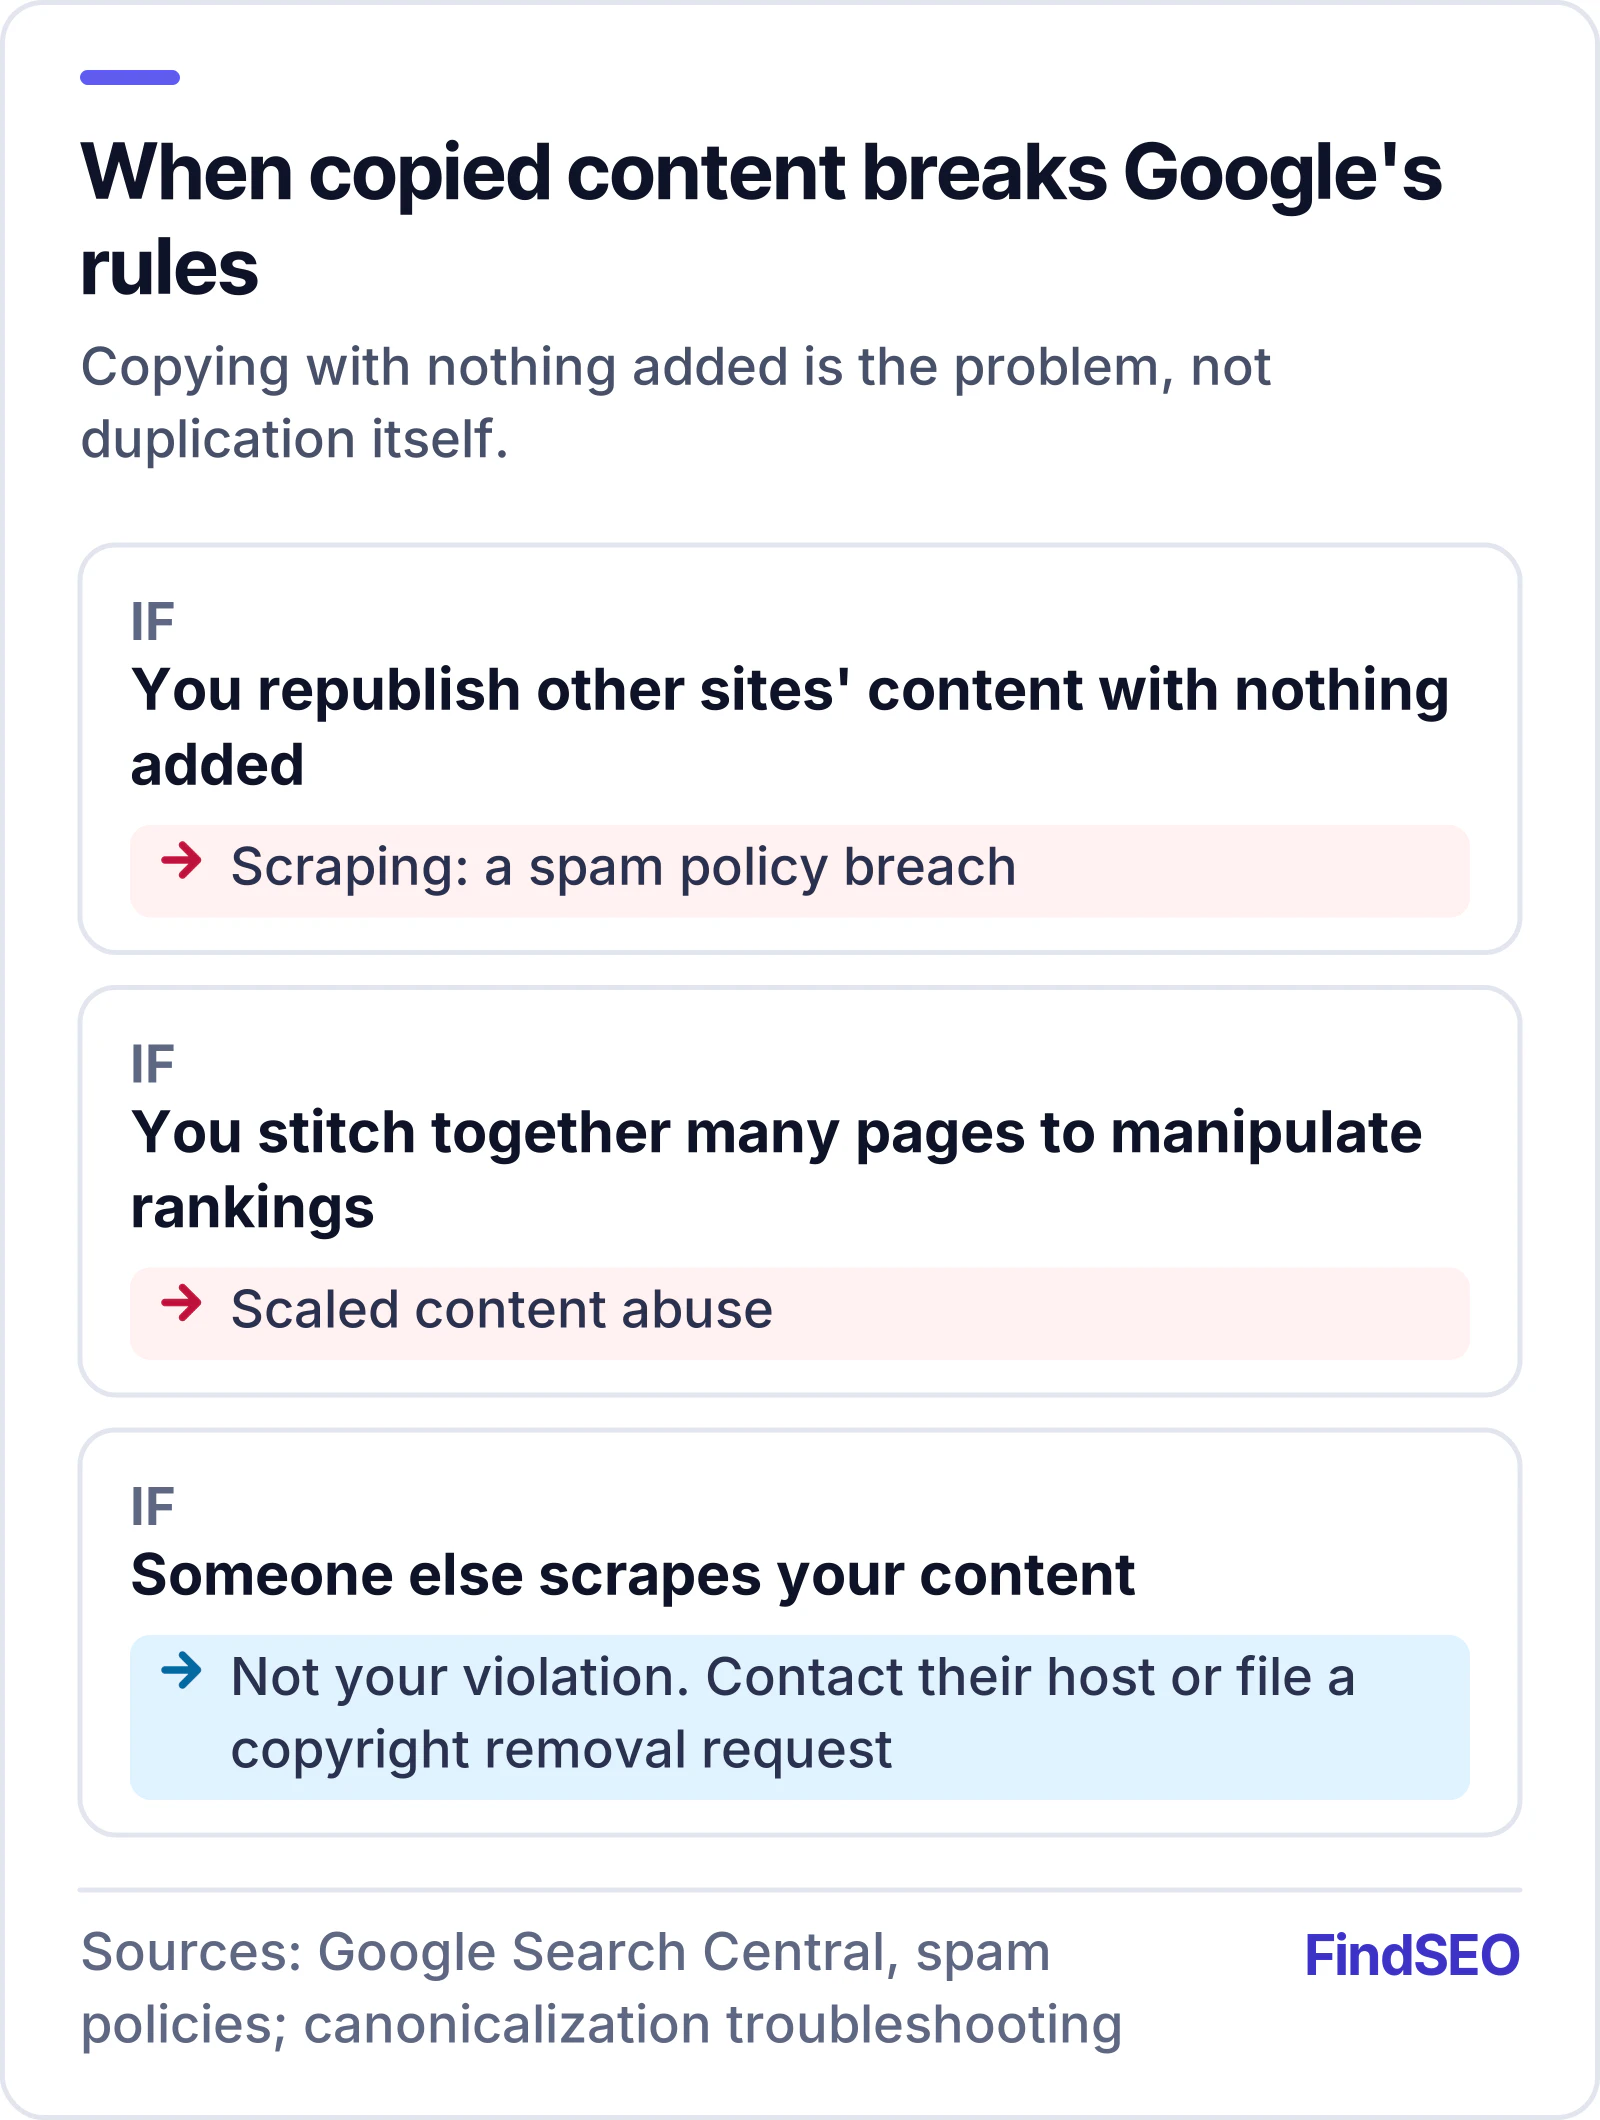
When it's copied from other sites with nothing added. Google's spam policies list scraping as abuse, including "republishing content from other sites without adding any original content or value, or even citing the original source," and copying content with only slight changes such as swapped synonyms. The same page describes scaled content abuse: generating many pages mainly to manipulate rankings, including by stitching together content from other pages without adding value.
Sites that break these policies can rank lower or drop out of results, and some get a manual action. Our Academy lesson on Search Essentials and spam policies explains how Google handles manipulation more broadly, and our guide to Google's spam policies covers scraping alongside the other policies.
Being copied is different from copying.
Being copied is different. Google's 2008 post notes that while scraping others is discouraged, "having others scrape you is a different story." If a copycat site outranks you, Google's canonicalization troubleshooting page says you can contact the site's host or file a copyright removal request with Google.
How do you tell Google which page is the main one?
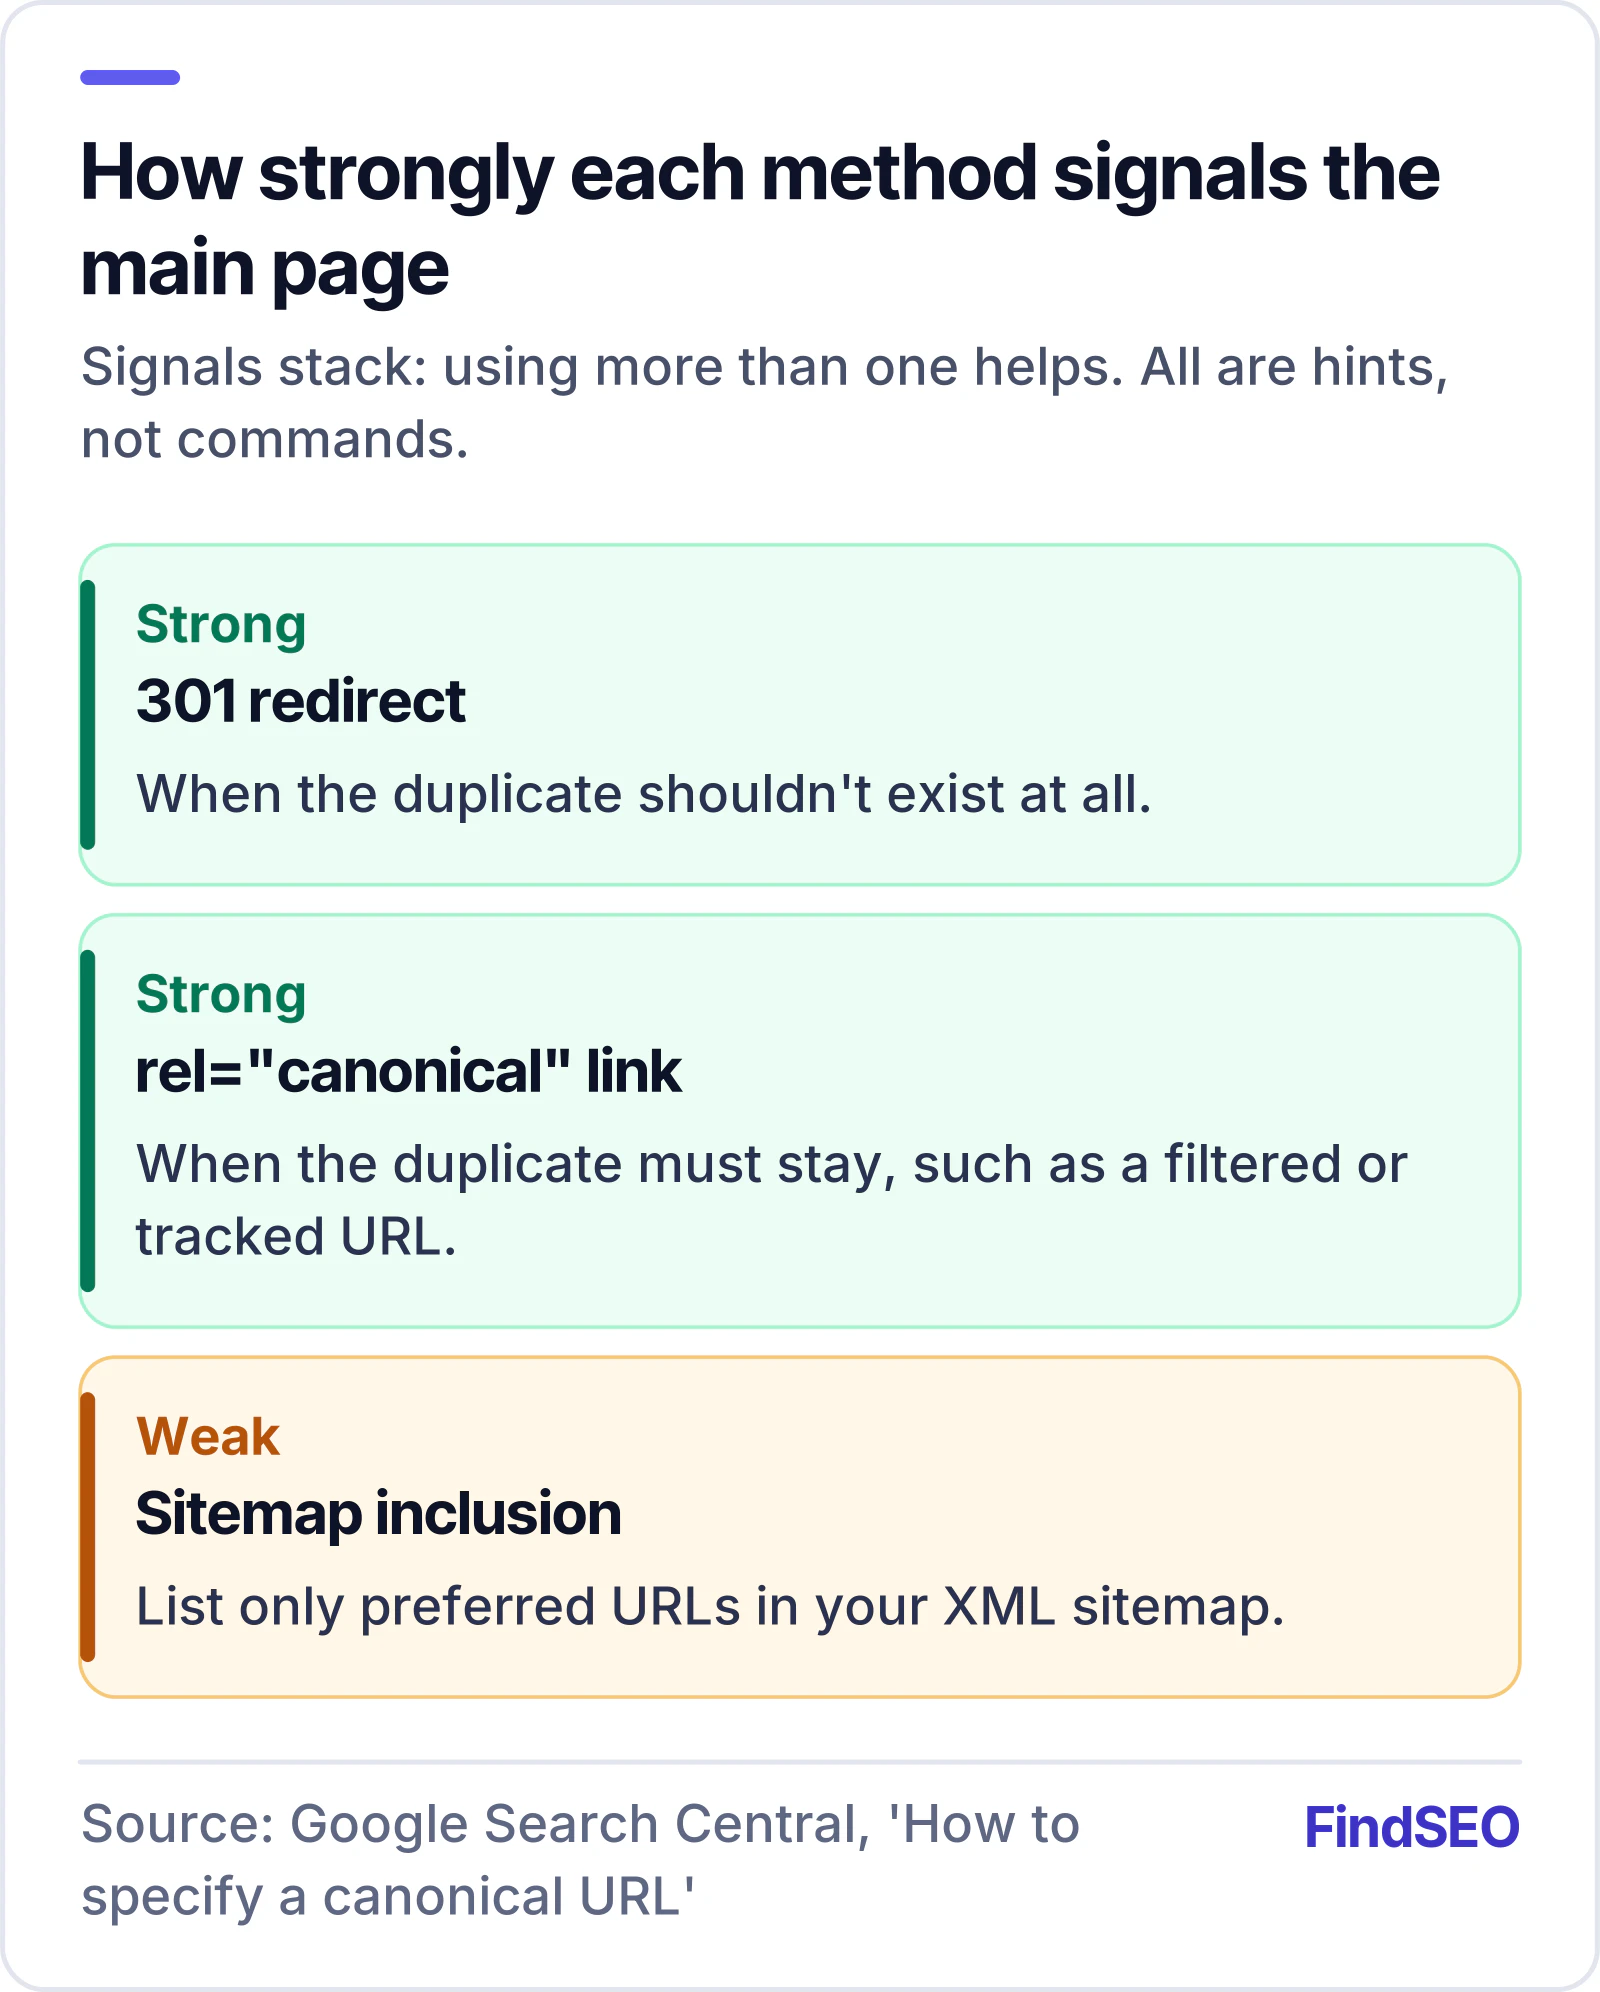
Google's guide ranks its methods by how strongly they influence the choice:
Redirects (strong). If a duplicate page shouldn't exist, send people and crawlers to the main version with a permanent 301 redirect. Google's page on redirects and Google Search says permanent redirects tell its indexing pipeline that the target should be canonical. You can confirm each one with our free redirect checker.
A rel="canonical" link (strong). When the duplicate needs to stay, such as a filtered or tracked URL, add a canonical tag in the page's head pointing to the main version, and a self-referencing one on the main page itself. Our guide to canonical tags and when you need them walks through how to add the tag and the mistakes that undo it.
Redirect what shouldn't exist, canonicalise what must stay, and keep the sitemap consistent with both.
Google says these signals stack, so using more than one increases the chance your preferred URL is chosen. They're still hints, not commands, and Google adds that none of them are required: if you do nothing, it will pick the best version itself. If you're consolidating old articles rather than fixing technical duplicates, our guide to how often to update website content covers when to update, merge, redirect or remove a page.
Mistakes to avoid
The same guide lists practices that backfire:
Using robots.txt to hide duplicates. Google may still index a blocked URL without its content.
Using noindex to choose a canonical. It removes the page from Search entirely, so rel="canonical" is the preferred fix.
Sending mixed signals, such as one URL in your sitemap and a different one in the canonical tag.
Linking internally to duplicates. Link to the canonical URL throughout your site. Our lesson on internal links, URLs and images covers clean linking.
Relative canonical URLs. Google supports them but recommends absolute URLs, because relative ones can cause problems if a test site is ever crawled.
For sites serving several countries in one language, Google recommends combining canonical tags with hreflang annotations, as described in its guide to localized versions of pages. Our hreflang checker tests whether your tags line up, and our guide to international site structure explains when country domains, subdomains or subfolders make sense.
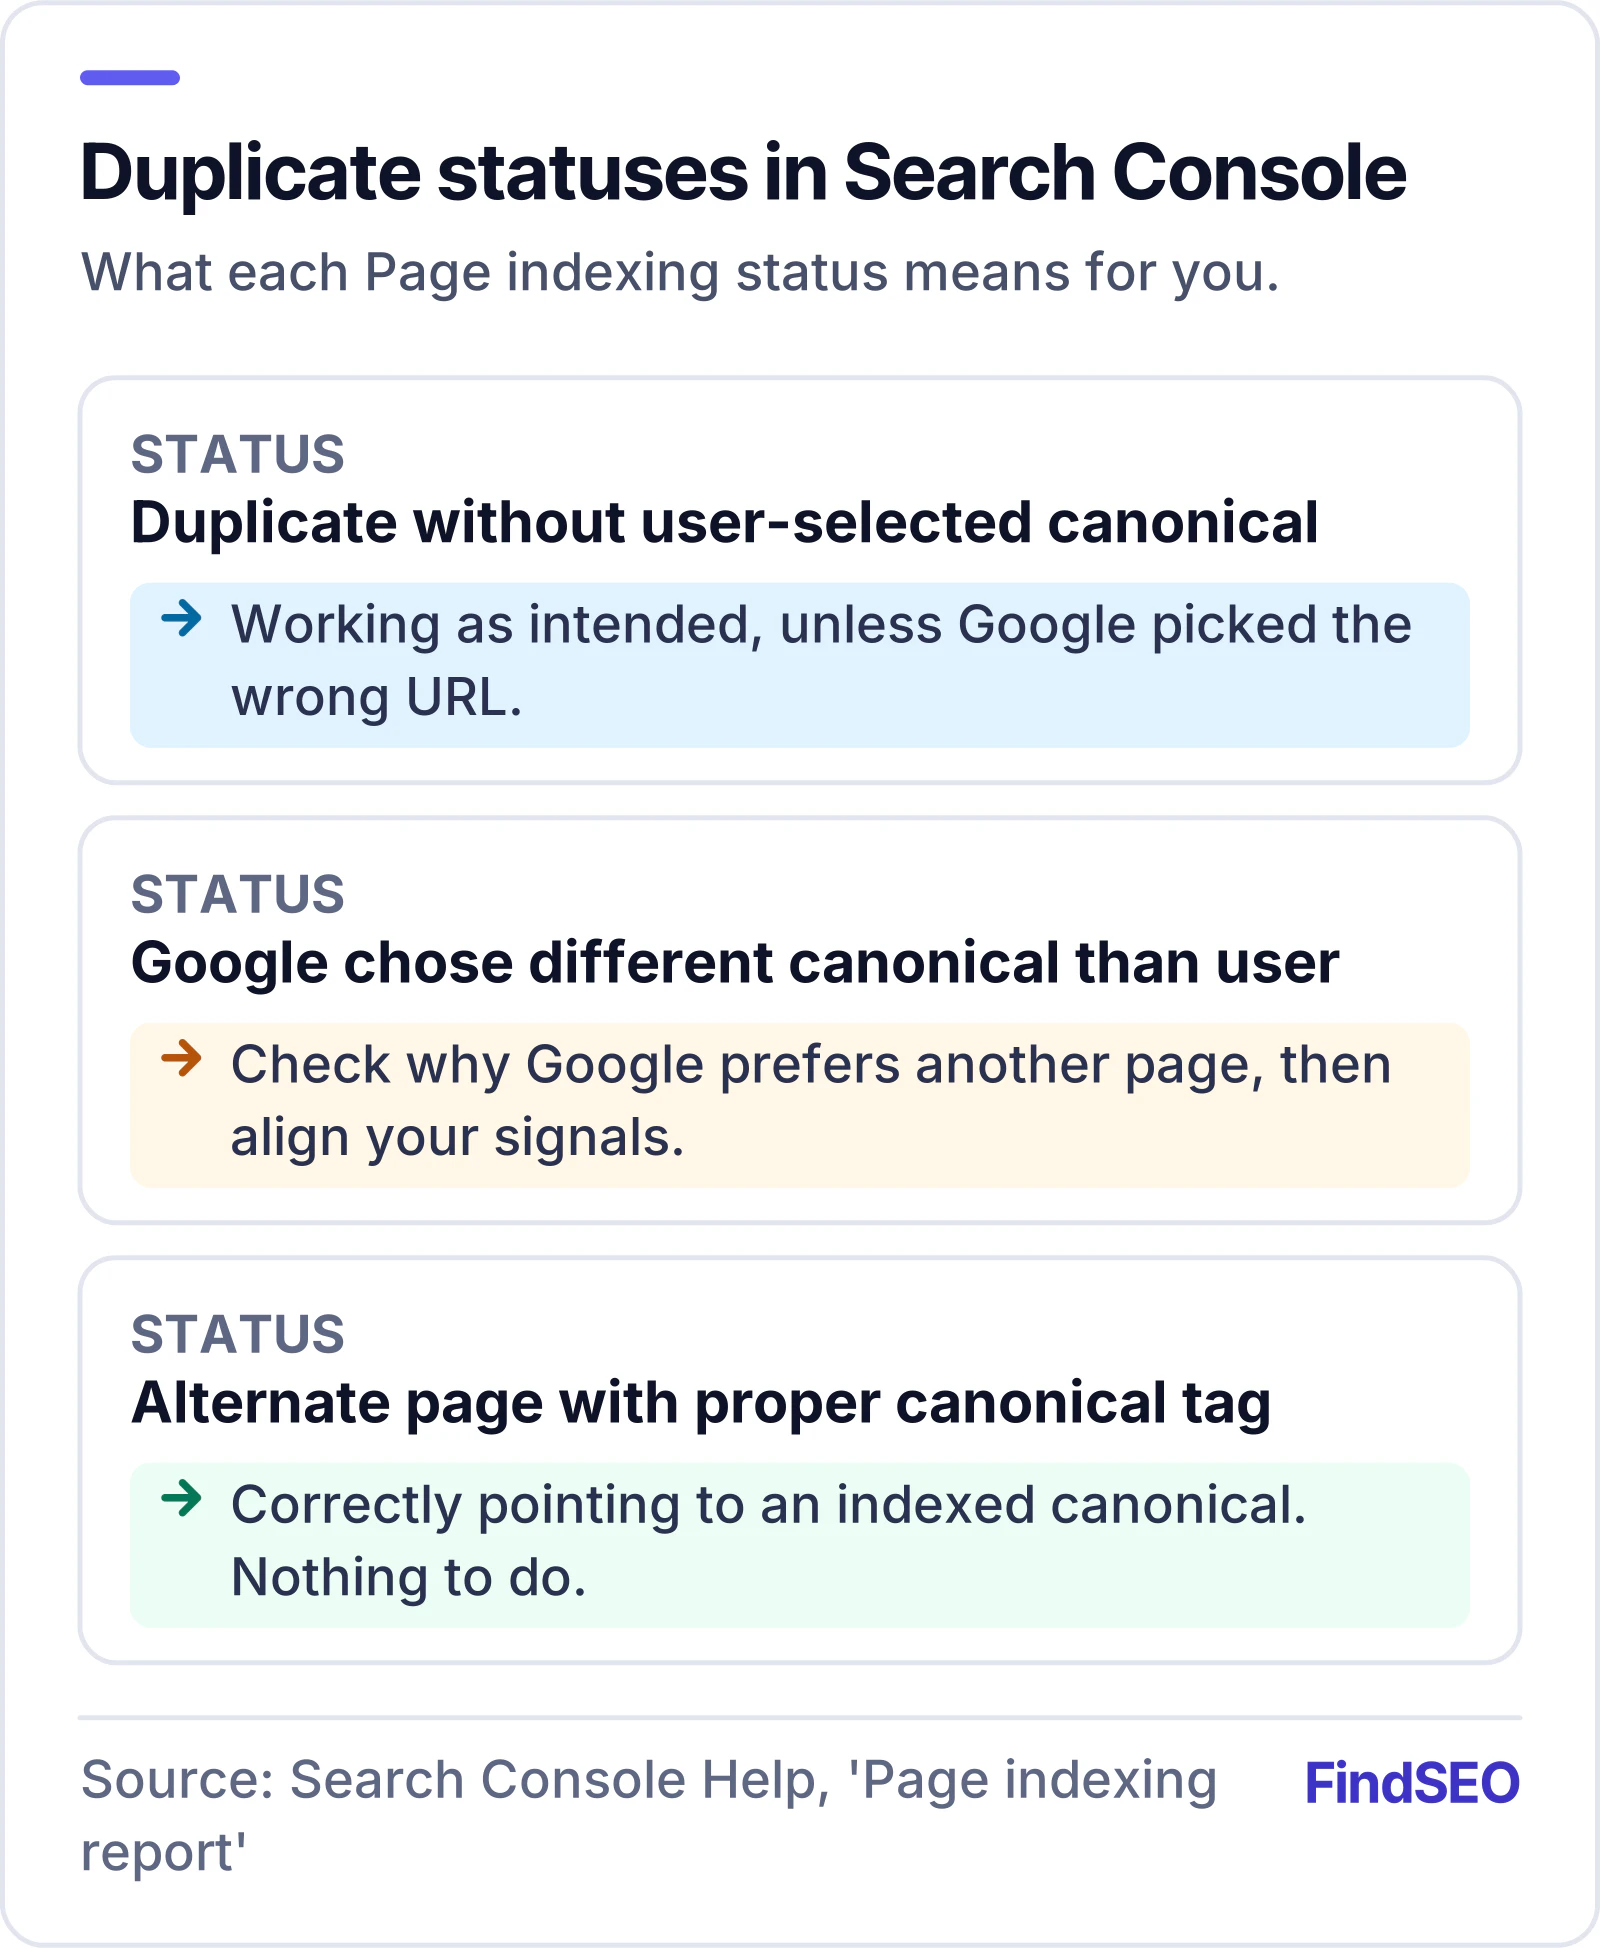
Duplicate without user-selected canonical: the page doesn't name a canonical and Google picked another URL. Google says this is working as intended unless it picked the wrong one.
Duplicate, Google chose different canonical than user: you named a canonical, but Google thinks another page is the better choice.
Alternate page with proper canonical tag: the page correctly points to an indexed canonical, so there's nothing to do.
Only the middle status usually needs your attention.
To check one URL, the URL Inspection tool shows both the canonical you declared and the one Google selected. Our free Google index checker is a quick first look: it reads a page's canonical tag, redirects, noindex and robots.txt rules before you open Search Console.
For copied text, our free plagiarism checker shows whether your wording already appears on other websites. Duplication on bigger sites is a standard part of a technical SEO audit, so ask your agency to include it.
What about product descriptions and syndicated articles?
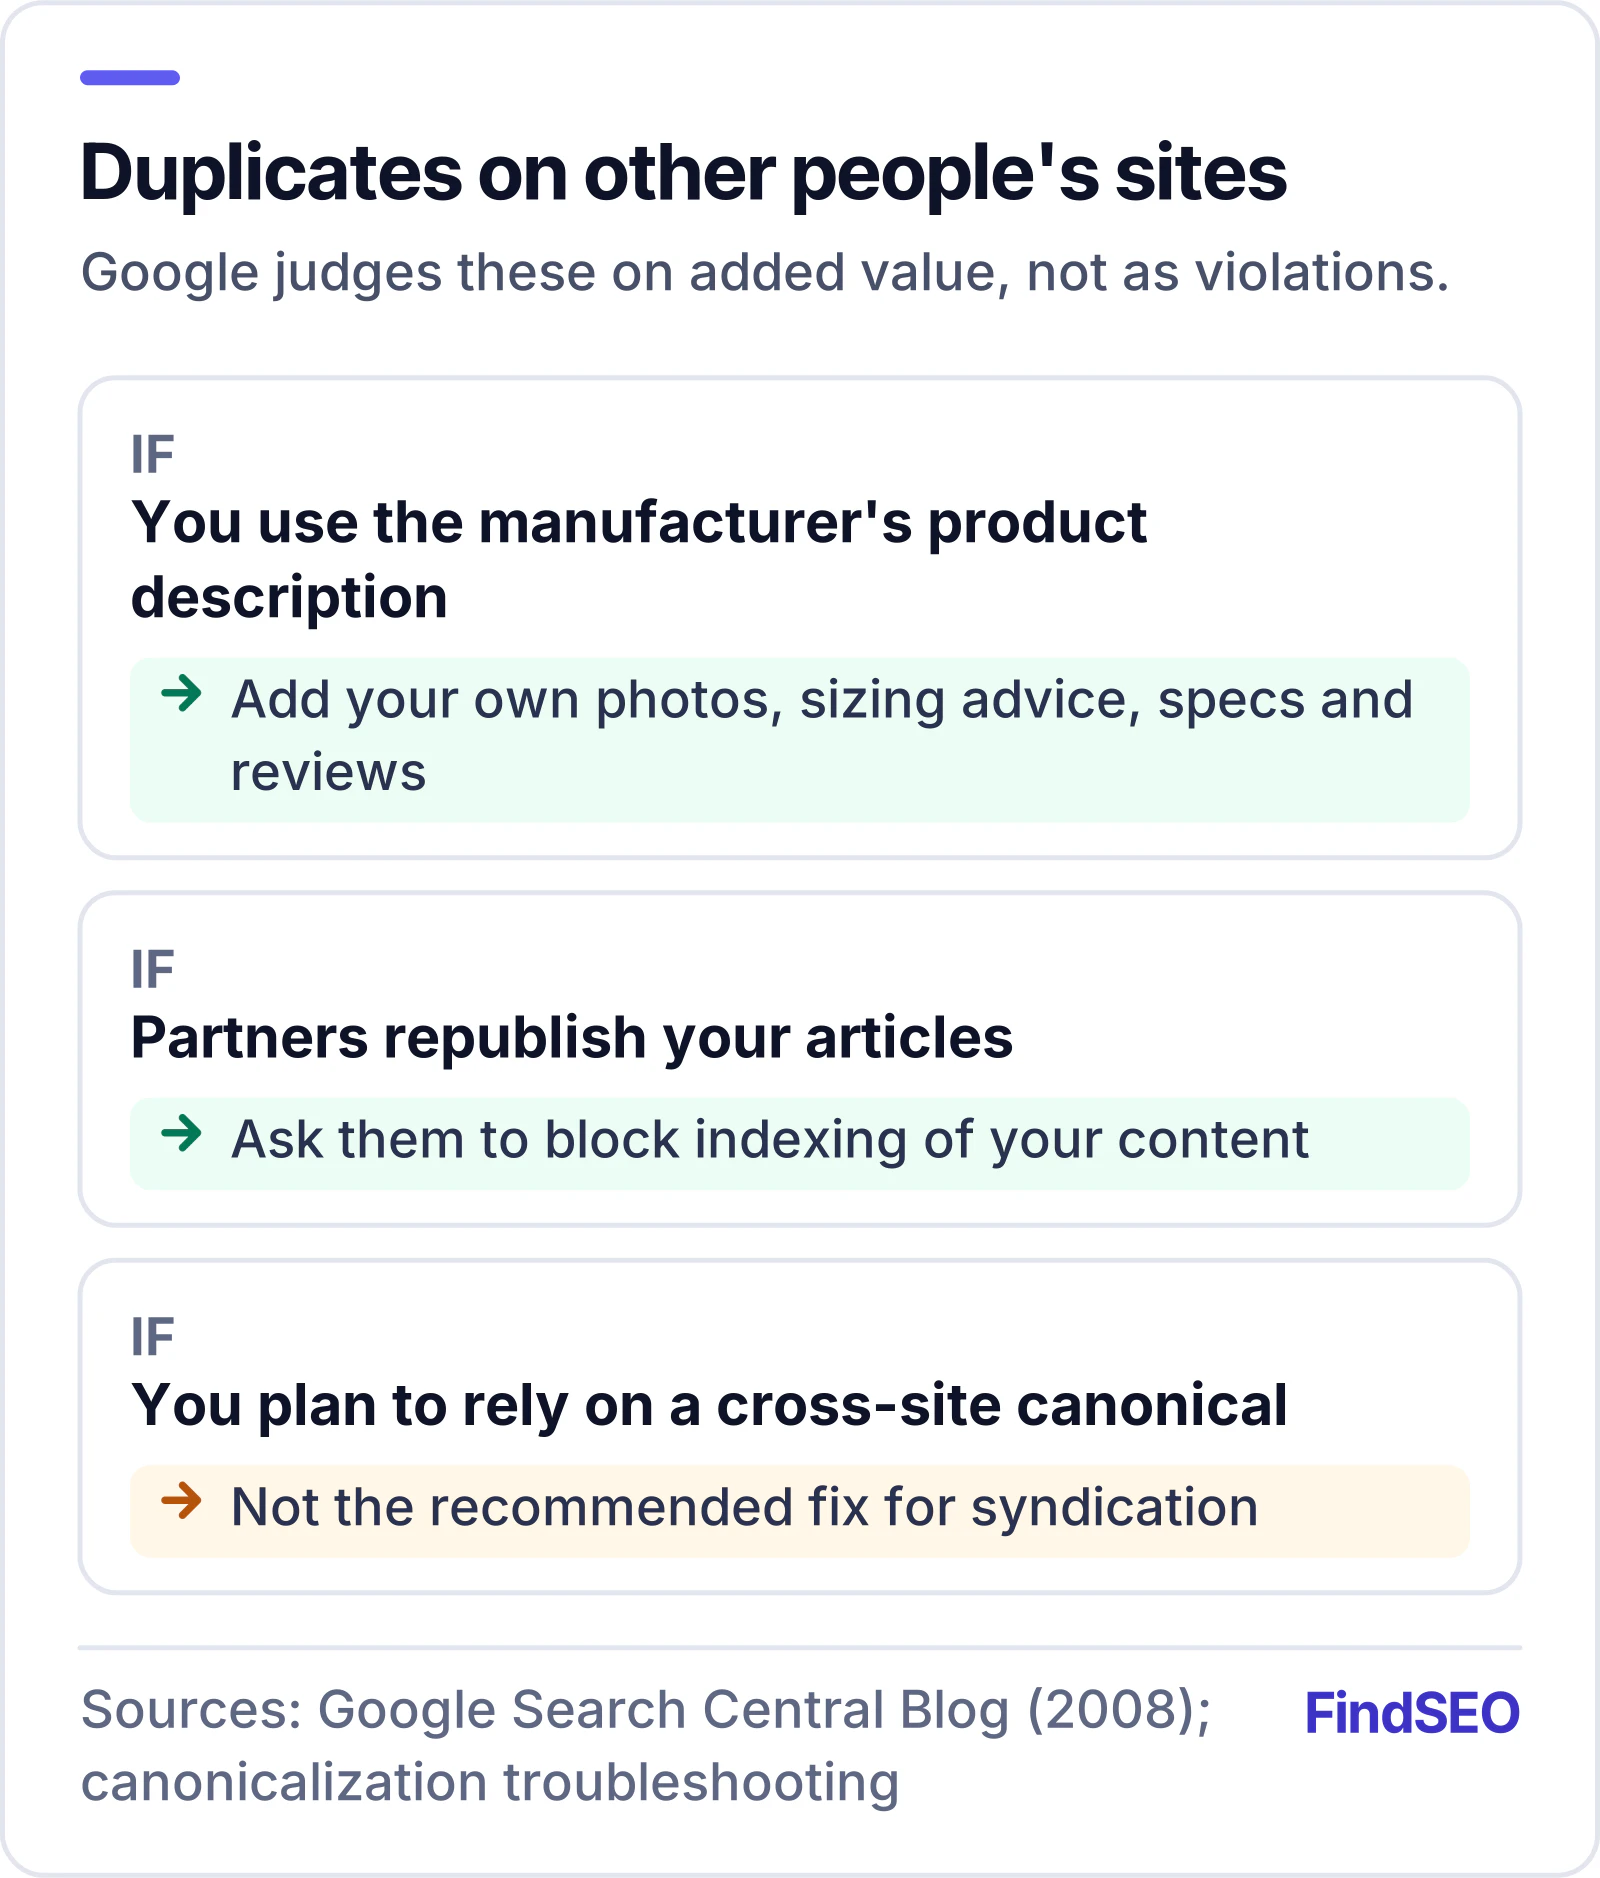
These are cross-site duplicates, and Google treats them on value rather than as violations.
Manufacturer product descriptions. Many retailers use the same supplied text. Google's 2008 post gives the example of affiliate sites struggling to outrank the original retailer with the exact same listing: searchers probably want the original "unless the affiliate site has added a significant amount of additional value." Your own photos, sizing advice, specifications and genuine reviews give Google a reason to show your page. Our helpful content self-assessment is a useful lens.
Syndicated articles. If partners republish your content, Google's troubleshooting page says a canonical tag isn't the recommended fix, because the partner pages are often very different. The most effective option is for partners to block indexing of your content.
Give Google a reason to show your version.
Duplicate content checklist
If the report shows other reasons as well, our guide to why pages aren't indexed and how to fix them covers each one. Work through this list once, then check the Page indexing report monthly:
One version of the site loads (HTTPS, with or without www), and the others 301 to it.
Every indexable page has a self-referencing canonical tag with an absolute URL.
Filtered, sorted and tracked URLs point their canonical at the main page.
The XML sitemap lists only canonical URLs.
Internal links and navigation use canonical URLs.
Staging and demo sites are password-protected or blocked from indexing.
Regional versions in the same language use hreflang plus canonicals.
Product pages add original detail beyond the supplier's description.
Search Console shows no important pages under "Google chose different canonical than user."
Old pages removed in a redesign or site migration redirect to their closest replacement.
Bottom line
Everyday duplicate content doesn't get you penalised, but it does leave Google to make choices you'd rather make yourself. Redirect what shouldn't exist, add canonical tags to what must stay, keep your sitemap and internal links consistent, and put your effort into original content rather than copies. If your site is large or the Page indexing report is full of duplicates, a technical SEO specialist can map and fix it quickly. Get matched with agencies that do this work, or browse the SEO agency directory.
FAQs
Will Google penalise my site for duplicate content?
Not for ordinary duplication like the same page at several URLs. Google says duplicate content isn't grounds for action unless it's meant to deceive and manipulate results, such as scraping other sites without adding value.
Should I use noindex or a canonical tag for duplicate pages?
Use a canonical tag. Google doesn't recommend noindex for choosing a canonical within a site, because it removes the page from Search completely. A permanent redirect is better still if the duplicate doesn't need to exist.
Why did Google ignore my canonical tag?
Google treats canonical tags as a strong hint, not a rule. It may pick another URL because of content quality or technical signals, such as mixed signals between your sitemap, redirects and internal links. The URL Inspection tool shows which URL Google selected.
Can I use the same product descriptions as other retailers?
It isn't a policy violation, but it gives Google little reason to rank your page over the original. Add your own photos, specifications, sizing advice and reviews so your page offers something extra.
How long does Google take to fix duplicate pages after changes?
Google says it may keep pages in a duplicate cluster for up to two weeks after content is fixed. You can use Request Indexing in the URL Inspection tool for important URLs, though it's subject to quotas.
Internal links connect your own pages so people and Google can find them. How crawlable links work, what anchor text to write, and a practical checklist.